Built by Engineers Who Ran Trading Infrastructure
Every design decision at EurekaLabs traces back to a specific failure mode we hit, observed, or had to architect around at the firms where we built these systems before.
Why We Started EurekaLabs
The founding team spent years building and operating low-latency trading infrastructure at quantitative hedge funds and proprietary trading firms. The work was good, but the tooling was not.
Every firm we came from had built the same feed handler, twice. Every firm had their own latency monitoring stack, mostly in spreadsheets. Every integration project started with a weeks-long FIX conformance process that should have taken hours. The underlying problem was not that the technology was hard: it was that institutional-grade infrastructure had no shared platform to build on.
EurekaLabs is that platform. We extracted the architecture patterns that actually worked at production scale, rebuilt them from scratch without the accumulated technical debt, and wrapped them in an API that a new quantitative firm can integrate without hiring a team of systems programmers.
The People Running EurekaLabs
Dmitri Sotnikov
CEO
Deep background in order routing and execution systems across quantitative trading environments. Led infrastructure rebuilds after two major latency incidents. Founded EurekaLabs to make what he built available to firms that cannot afford to build it in-house.
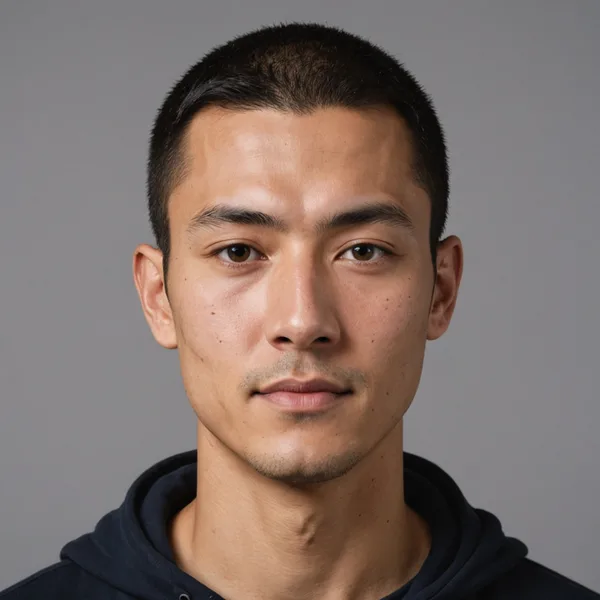
Haruto Yamane
CTO
Systems programmer specializing in kernel-bypass networking and FPGA co-processing. Built low-latency execution paths for futures strategies across Asian and US exchanges. Author of several articles on the EurekaLabs Pulse blog.
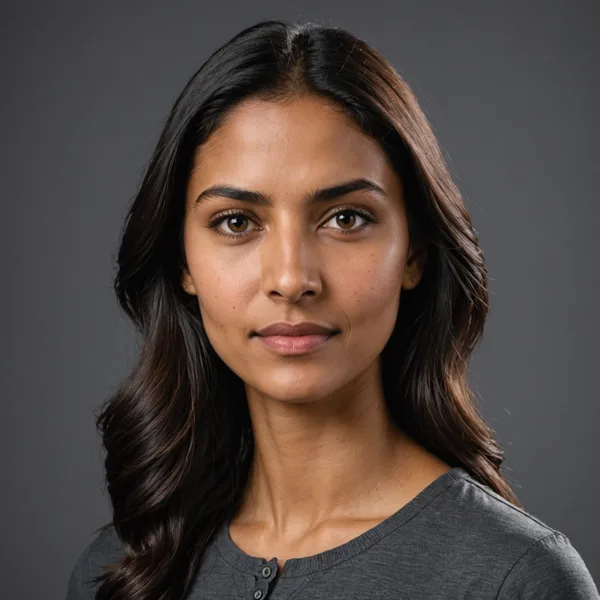
Priya Venkataraman
Head of Data Infrastructure
Feed normalization and tick data architecture background spanning multiple venue formats and aggregation pipelines. Built the reference conformance test suite for EKL Unified Stream. Leads client onboarding for firms with complex multi-venue feed requirements.
What Guides How We Build
Measure, Don't Claim
Every latency number on this site comes from hardware timestamps in production conditions. We publish p50 and p99, not just best-case. If we cannot measure it, we do not claim it.
Depth Over Breadth
We cover fewer asset classes and venue types than some competitors. What we cover, we cover completely: full order type support, full venue connectivity, and documented failure recovery for every path.
Clients See What We See
The same latency dashboards and audit trails our operations team uses are available to every client via the management API. We do not have a separate client-facing view that smooths over the raw numbers.
Interested in Working at EurekaLabs?
We are a small team and we hire slowly. If you have a background in low-latency systems, feed handler engineering, or quantitative infrastructure, we would like to hear from you.